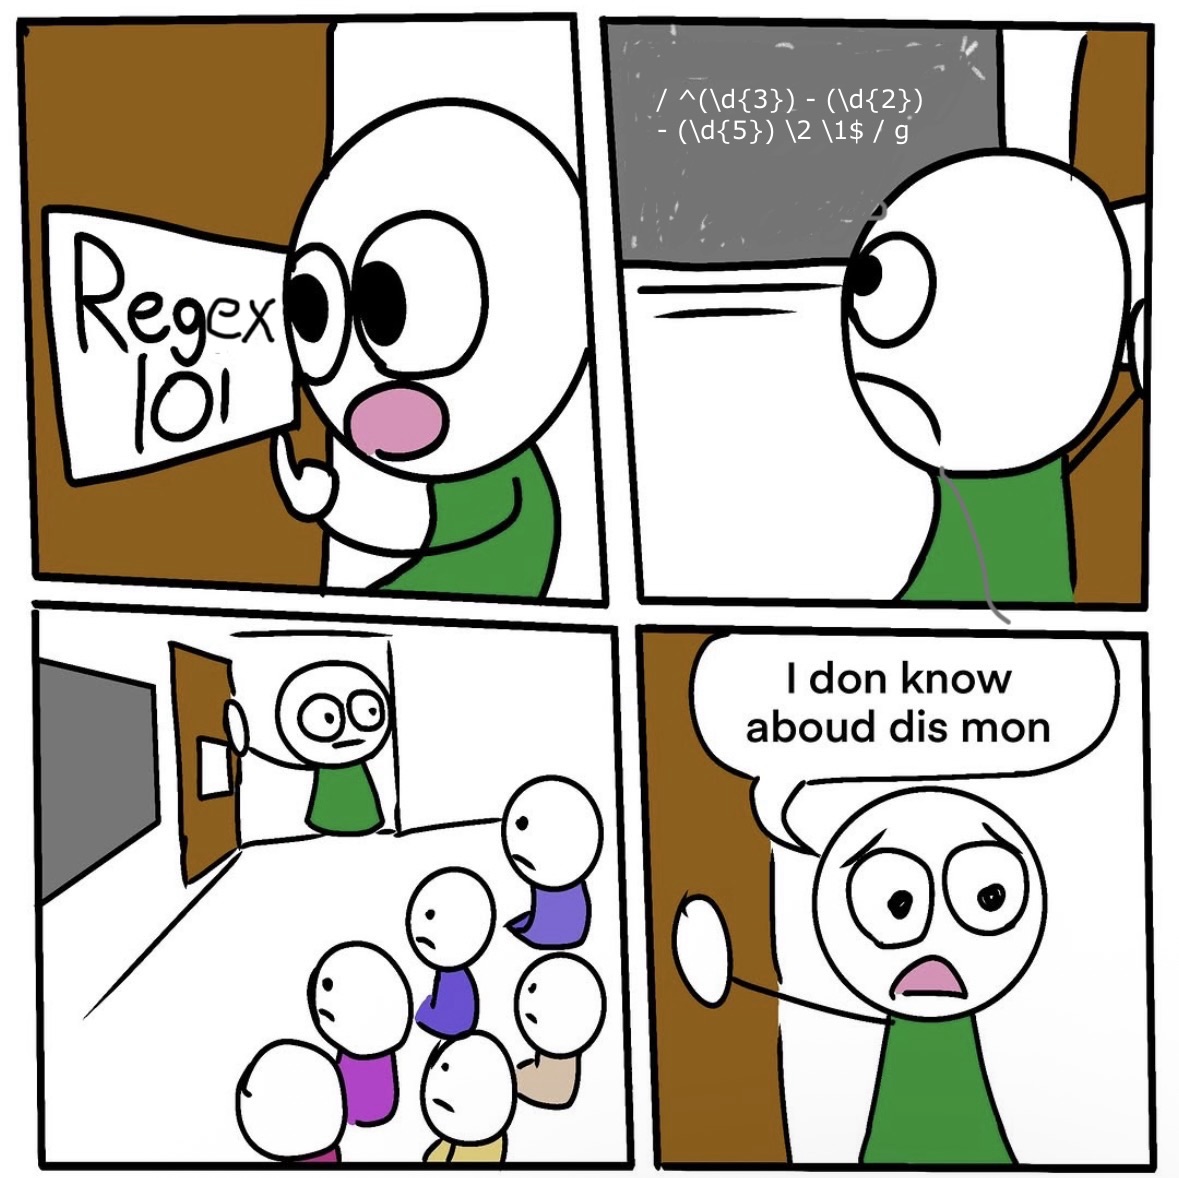
As someone who doesn't know any regex syntax, is there any simple explanation for what the expression on the board does?
post
A couple of years ago, there was a guy wanting to use some llm-based agentic whatever to extract a specific information from a group of research articles in pdf. His justification was that it was a complex kind of information that needed to be extracted. After the same task was assigned to me, I dumped the llm and did the same thing, with fewer errors and much faster, by just using some regex patterns with pdfgrep. It can be complicated, but it's so powerful! And I don't even know shit about regex, I just used a search engine and some trial and error lol
this inspired me to make another shitty meme here u go enjoy: https://lemmy.cafe/post/36565281
Ugh I don’t miss having to parse someone else’s regex at my old job.
Is there a version of regex with comments?
I mean one would typically insert it as a literal in another language but if there are flexible macros it could be done without any runtime cost/standard reinventing.
PCRE supports inline comments:
foo(?# match literal foo)\d+
Also verbose mode
pattern = re.compile(r"""
^ # start of string
[A-Z]{2} # two uppercase letters
\d{4} # four digits
$ # end of string
""", re.VERBOSE)
I've seen attempts of regex pre-processors, where you'd get some builder API like:
pattern
.digits(3)
.literal(" - ")
Can't use that in configurations, though, unless you template the configuration, I guess...
There is Backus-Naur form (and it's derivatives), which at least lets you name each section of text like you would a variable or function. Technically matches context-free expressions rather than regular ones but that's hardly different for most cases.
Emacs has the rx macro: https://www.gnu.org/software/emacs/manual/html_node/elisp/Rx-Notation.html
Backreferences are bad for performance and make the grammar being matched irregular, if I remember my comp sci classes. I don't they should be taught in a Regex 101 class.
Are you thinking of lookarounds? Backreferences do have some performance impact but a lookahead or lookbehind much more so. That definitely breaks the regularity, but I'm not sure that applies to backreferences (which may be my own ignorance). Performance wise unmatched lookarounds are the least performant getting worse as the size of the corpus increases. A positive lookahead/lookbehind has to scan all the text before or after the assertion to determine match failure and likewise negatives must do the same to determine match success. Greedier matching also amplifies things here (do you want just the first match or all of them?)
I'm more fluent in regex syntaxes than in the implementation details of any specific regex engine, so please correct me if you know Im wrong, both for my own edification and so that when I share things going forward Im sharing the most accurate information that I can.
Turns out we're both off the mark: it's catastrophic backtracking that is "dangerously" vulnerable to performance issues. Something as simple as (a+)+b is enough to trigger the "bad" behavior. I assume you can achieve it with back references and lookarounds as well.
This video gives a good breakdown of what exactly is going on inside a compiled regex automata that encodes such a case: https://www.youtube.com/watch?v=gITmP0IWff0
Thank you friend! I honestly had almost forgotten that you could + on a group (in extended syntax i think?) like you can with *. In my experience I find lots of * groups and I do my best to convert those to a range eg {3,5}. When you can't typically you can set least still use an open range floor {3,} or ceiling {,5}. I'm a big fan of explicit constraints when you have enough information to set them. It's another good maintainability practice in my experience. The more clear the regex the less example data you need to understand the intention. I especially like eg ruby's regexp.x flag that let's you ignore literal newlines and whitespace in the pattern (not to be confused with regexp.X which does the same but for the corpus), so you can split your pattern over multiple lines. I like to use indentations when it helps readability and that also allows a multi line comment header indented the same way. Sometimes you can even set inline comments depending on language/engine/syntax. For significant whitespace in the pattern wrap each whitespace character in a character class containing only itself: eg [ ][ ] for two literal spaces to match. This is also how I handle patterns for eg sed or grep in bash/zsh which have their own whitespace semantics, to get whitespace literals in your patterns without the need to escape anything. The non-literal part of the pattern doesnt change, and the literal part gets substituted in piped through something like sed -E '/./[\1]/g'
!onehundredninetysix@lemmy.blahaj.zone TIL, through a meme (yep, memes can be very teaching, too), that I can reuse capture groups in a recurring manner inside a RegExp (I didn't know about the (number) thing, but I readily inferred, due to past experience with using (number) in KDE Kate's Regexp replace, it had something to do with "this position must contain the nth group verbatim", opened the DevTools, tried .match with a fixed version of the meme's regex (i.e. without the invalid spaces) and a random phone sequence my mind conjured out of thin air, and voilá, the slash-number thing indeed behaved as I guessed it would behave). So... Thanks to whoever made the meme because TIL thanks to you!/^Be( )not\1(a)fr\2id$/ (Biblically-accurate RegExp).
This is a cool feature of a lot of regex implementations but I will warn you that reusing capture groups in a match means it's impossible for any regex engine to guarantee a reasonable upper bound (best they can do is O(n!) I think? I'd have to look up the details). In a replacement string this is a non-issue because there's no way they can recurse out of control.
Edit: found the video I originally heard this from: https://www.youtube.com/watch?v=gITmP0IWff0
And this is why I'm not a programmer
That's not a problem at all. Most programmers don't understand regex as well
you will find regex in numerous things that have nothing to do with writing code. i don't even need to leave firefox to find several instances in the addons i have installed.
I just ask an LLM if I ever need to create a regex query. Which is almost never hence I don’t understand regex. Many programmers don’t understand regex. Like when do you ever need regex if you program a game engine.

all 39 comments