I use gluetun, my arr stack and bittorrent client in a single docker-compose. I use the syntax

    depends_on:
      gluetun:
        condition: service_healthy

in the stack to make sure that the bittorrent client doesn't try to connect too early. All that works great.

I also use that same VPN connection for other containers too (not in the same docker-compose stack). I do that by simply using network_mode: "container:gluetun" in the second yaml file. But I'd like to use the same depends_on syntax. But it errors out because gluetun is undefined in the second stack.

So my question is, how do I make sure the containers in docker compose stack 2 start after docker compose stack 1 (the one with gluetun) is healthy?


I host my own instance of invidious behind a reverse proxy. It's awesome. I use Redirector for Firefox so that when I'm on the interwebs, YouTube videos and embeds redirect automagically to my self-hosted invidious instance. I used the setup instructions in the Invidious-Redirector documentation.

Recently, I was on a new website and the embed didn't redirect. I tried to figure it out, but couldn't. The best I could do was try changing /embed/* to /oembed/* but that didn't work.

So I thought I'd ask here: How would you go about setting up a rule or multiple rules to sort this?

Edit to add: If you go to the new website, make sure you either have AI chatbots blocked in uBO or create a rule ||autonomoustechnology.ai^. Otherwise there is an annoying AI chatbot that pops up that you'll want to block.


Original post here [redlib link].

Written by deluan

The next release normalizes every ID in the database into a single format. It runs a one-time migration on first start. The PR with this change will be merged this weekend: https://github.com/navidrome/navidrome/pull/5824

If you run develop or auto-update, this lands soon (this weekend) and without warning. Make a backup of navidrome.db now. The migration is one-way, so rolling back (if needed) means restoring that backup.

The short version:

  • Takes ~30s to ~1m20s on my 96k-track library (QNAP Celeron). Scales with library size.
  • Everyone gets logged out once. Web UI and clients using the Navidrome API need to log in again. Subsonic clients authenticate per request, so they are unaffected.
  • Song IDs change, album and artist IDs do not. Clients that cache song IDs (offline downloads, cached playlists) may need a re-sync.
  • Cover art gets re-fetched, so the first browse after upgrading is slower.
  • Share links keep working.
  • Nothing is lost: favorites, ratings, play counts, bookmarks, play queues, scrobble history and Last.fm / ListenBrainz links all survive. No rescan needed.
  • One manual fix: .nsp smart playlists using inPlaylist or notInPlaylist keep the old playlist ID on disk and need updating by hand.

Full write-up: https://gist.github.com/deluan/917ebc243c8b486101de857ffae6739b

If you can, please test it with your favourite client once it is merged, and reply here (or on our Discord) if anything looks off.

EDIT: For app/client developers: I'll merge the topSongsByArtistId PR at the same time as this ID migration. This means that you'll be able to detect if a server is migrated by checking the getOpenSubsonicExtensions response and looking for the topSongsByArtistId extension.

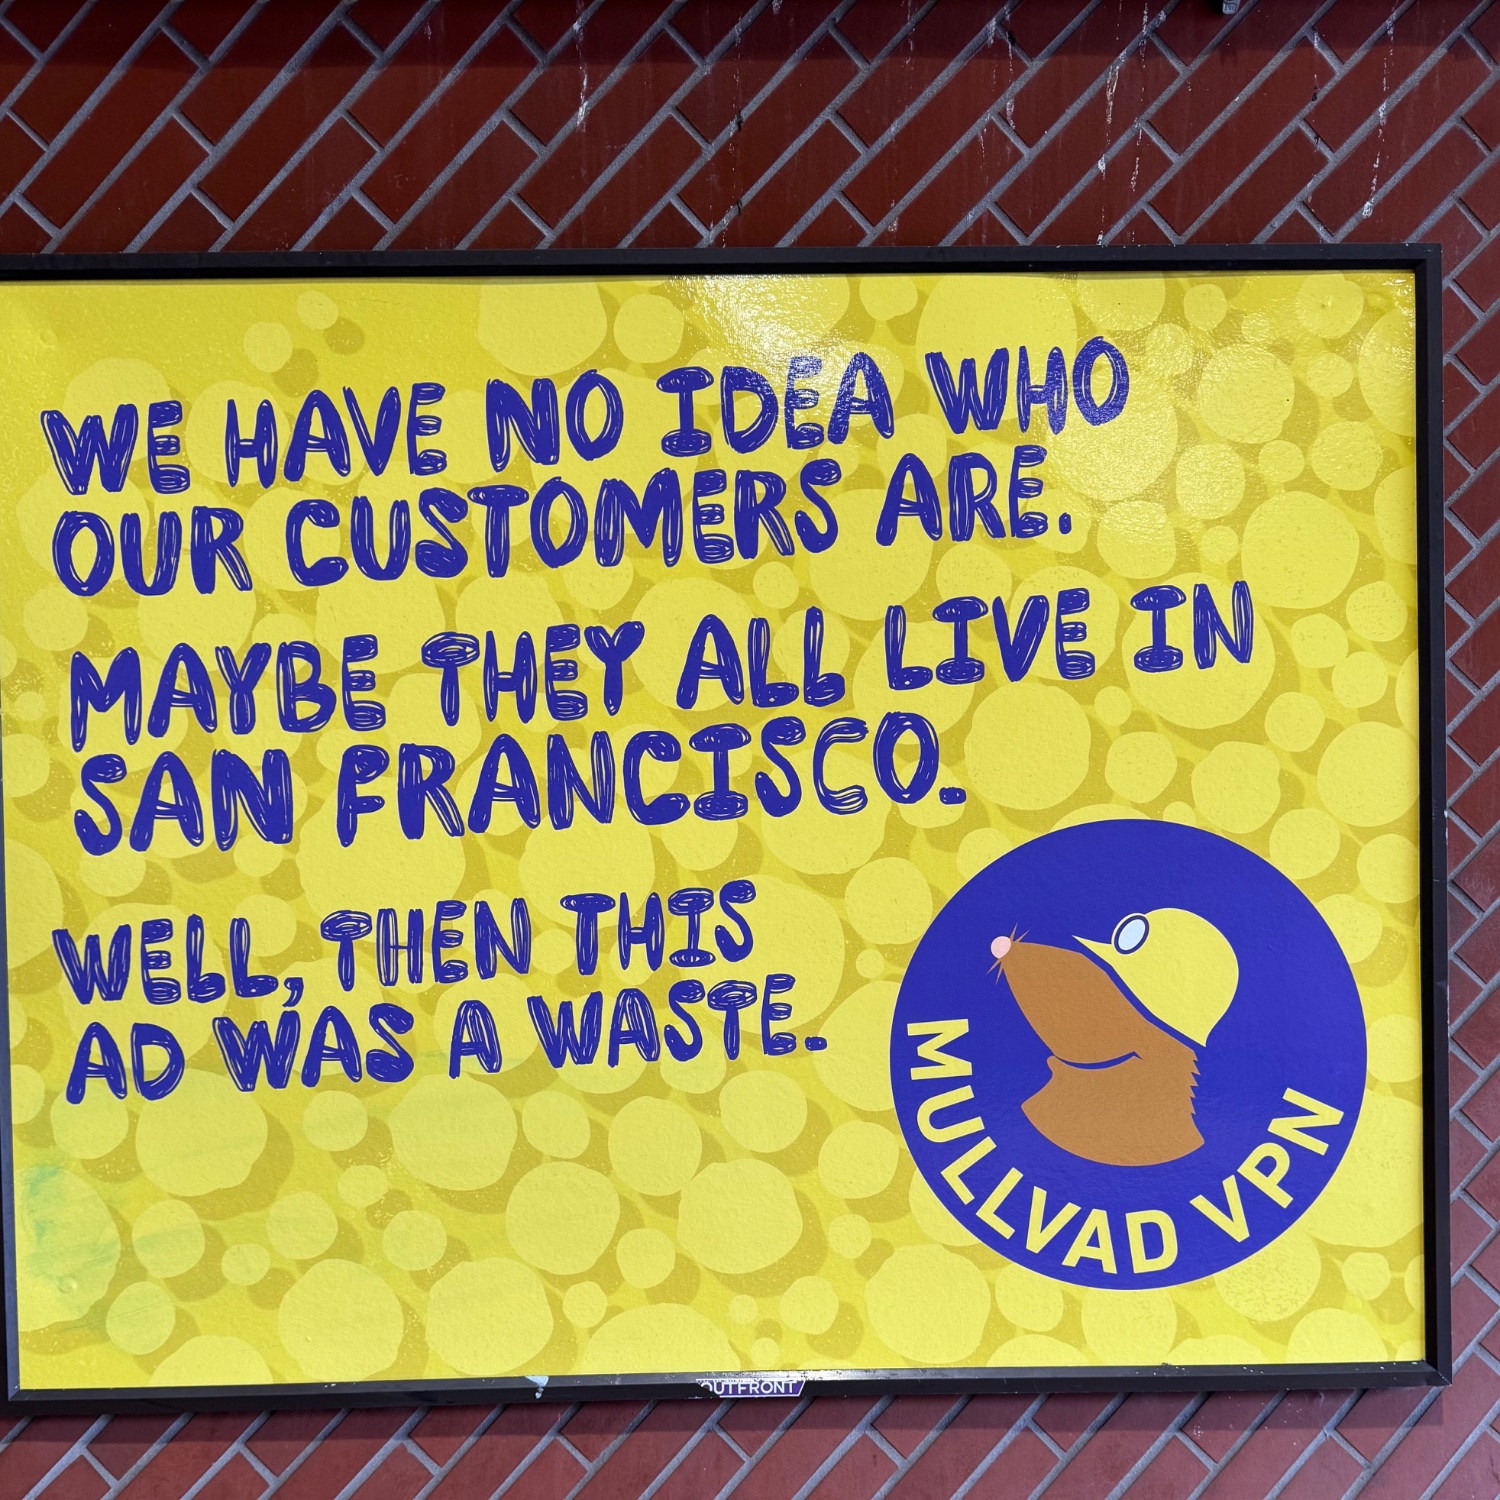
 

Seen in a SF Muni station

Edit to add: Jeez, relax. I was on my way home from a doctor’s appointment and saw that ad. It made me chuckle so I posted it here.

If seeing this post really upsets you, take some deep breaths and keep scrolling. With any luck, you’ll have fully healed in a couple of days.