Not that I'm aware.
Also, at least in my case, I use scripts to implement features on client side, like hiding posts by liking/disliking, or some redirect or similar buttons:

Not that I'm aware.
Also, at least in my case, I use scripts to implement features on client side, like hiding posts by liking/disliking, or some redirect or similar buttons:
...or maybe the login requirement was reactivated for everything and what I saw were the ripples of the small window it stayed active, given my test just now.
I just ran a curl https://kbin.earth/feed -H 'Accept: application/rss+xml' command, and it did return the expected RSS XML response.
Appears to have been the solution. Tested a link yesterday night, after BentiGorlich's comment on the spike graph, and the direct links are back to being login-protected, though now feeds seem to be working.
It should be working right, as long as the RSS client sends an Accept header equal to application/rss+xml.
So it is just the login requirement or did I miss something else? Allowing anonymous access to the endpoint would solve it then, but makes it also easy for scrapers to fetch content.
The error with kbin.earth is likely that the /feed endpoint is not excluded from the Cloudflare protection.
You can send albums, but unfortunately Mbin can not read them.
Well when I remove the requirement to login this happens. I guess you know what happened in the middle :D
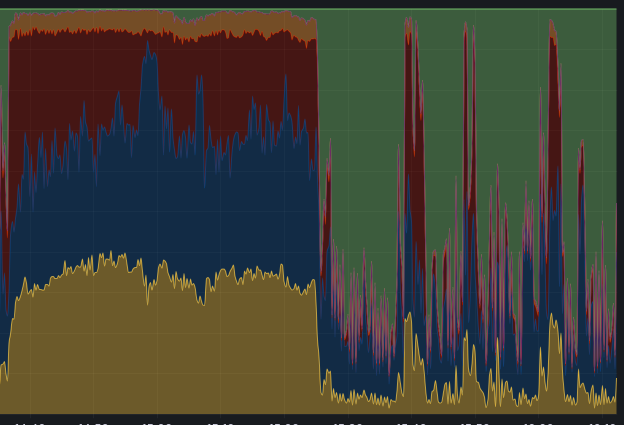
Seems to be the case? Left an instance of Newsboat running as I went to do my chores, and just checking now, it already fetched a few communities' posts.
Though it seems concerning to me that scrappers are getting past the current protections. (Hopefully I'm not one of them, considering how much I still follow...)
oh okay, well yeah I enabled the "force users to login" option, because the scrapers are just causing tremendous load otherwise. On gehirneimer it is currently disabled so maybe that is the sole reason?
(4/4) Remembered I could ask some AI to make things easier.
For kbin.earth feed, Grok says it's Cloudflare bot protection, likely because neither Newsboat or Feeder pass a valid browser agent.
For TBB, Grok for some reason had a hiccup, so asked GPT-5.4 on DuckDuckGo's AI bridge, and it said:
The problem is that the URL is not returning a valid RSS/Atom feed. It’s returning an HTML login page instead, so feed readers see a normal webpage with , , etc., not feed XML. That’s why one reader says “no feeds on the page,” another says “unsupported feed format,” and another says “malformed xml string.”
From the pasted page, the site is protected by login and the feed endpoint appears to require authentication or is redirecting to the login page. The presence of a CSRF token and sign-in form confirms the response is HTML, not feed data.
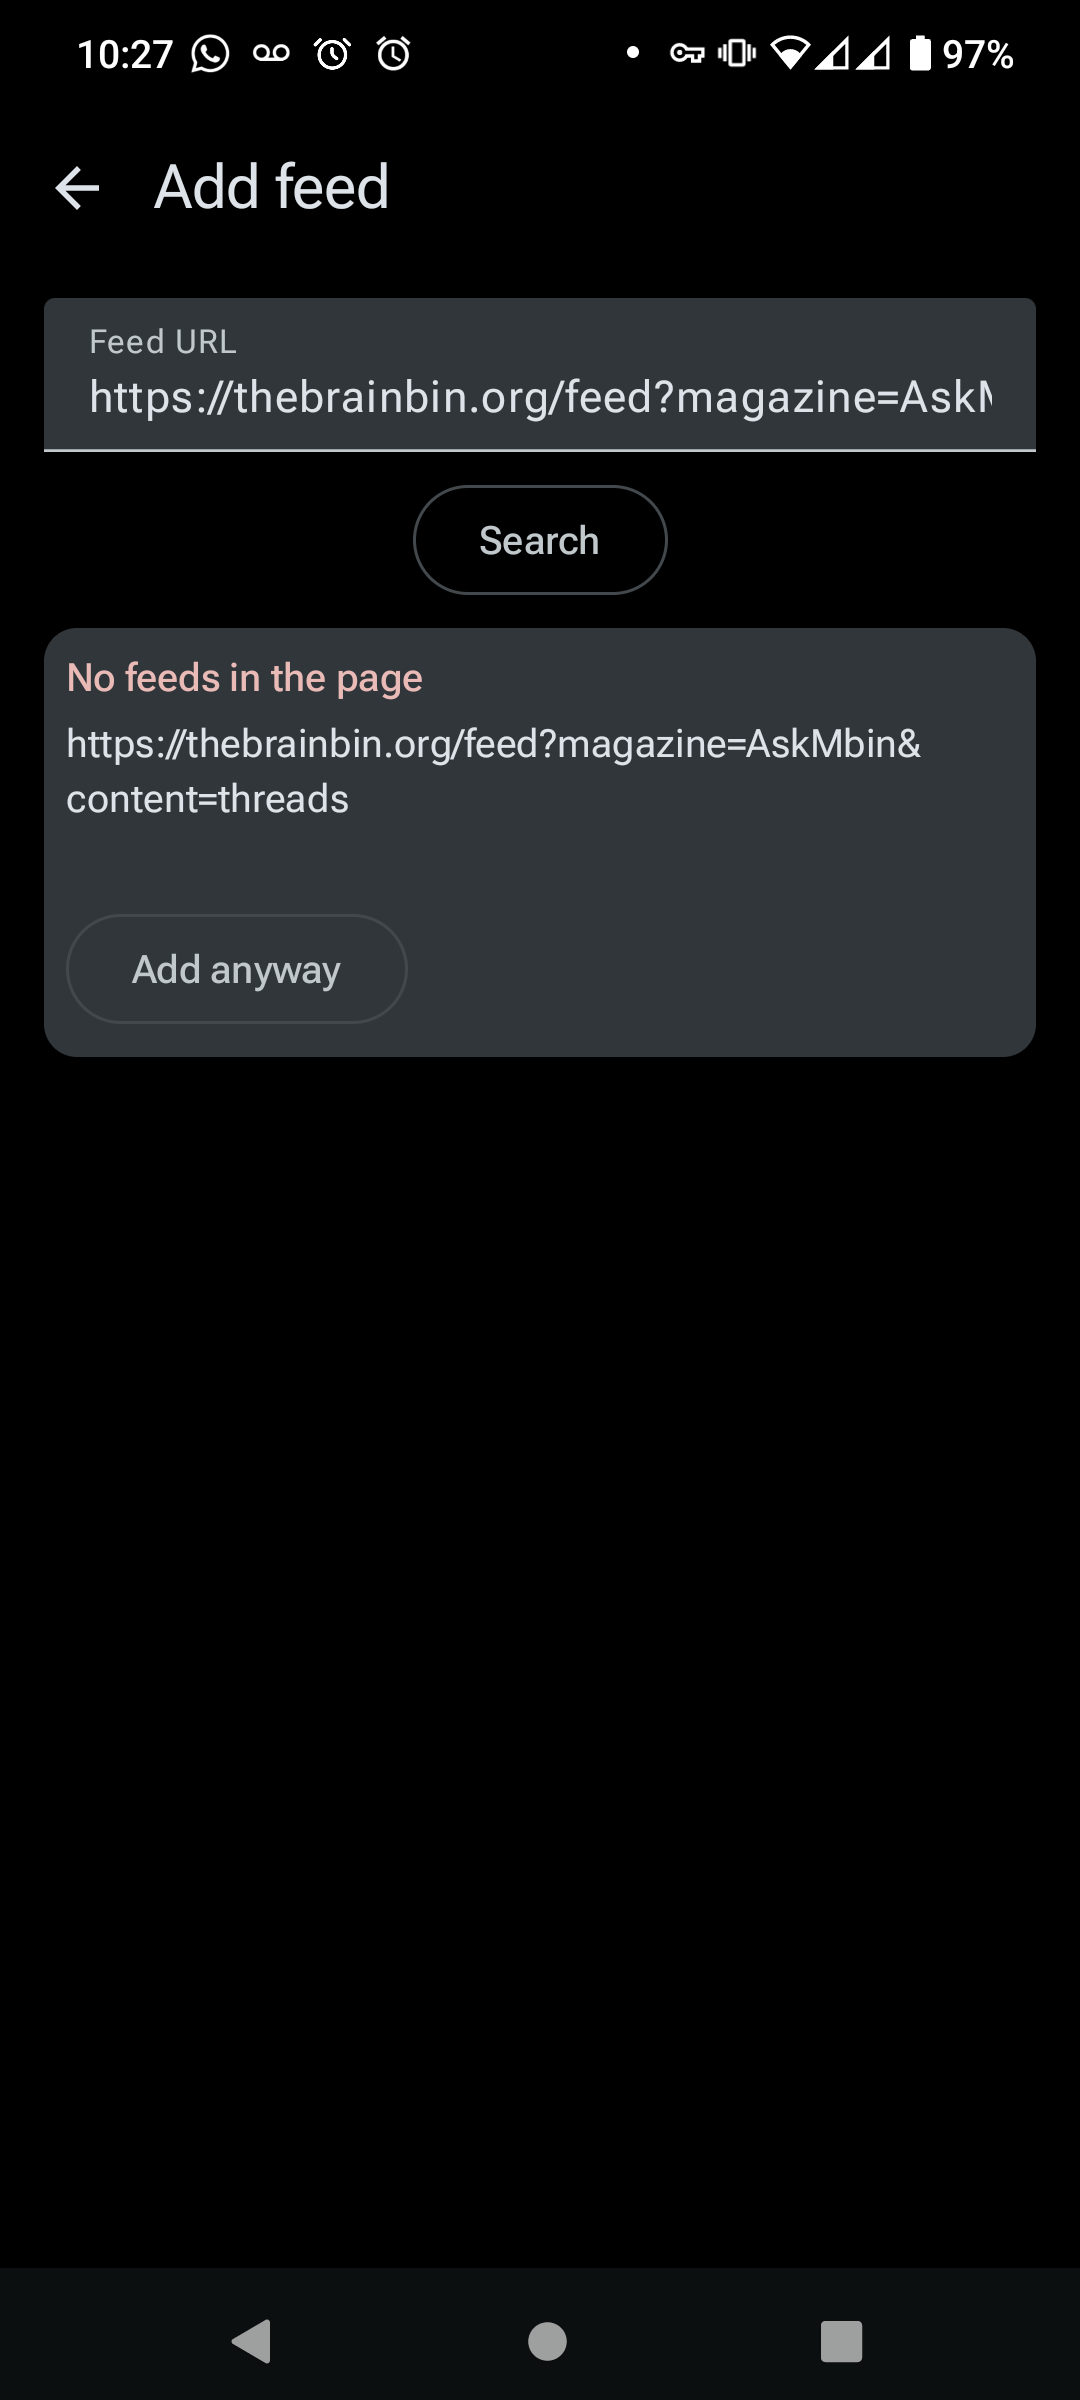
(3/4) (Just remembered I could send albums through my alt)TBB & kbin.earth errors on Newsboat when trying to reload feeds during my tests at the time of writing the post:
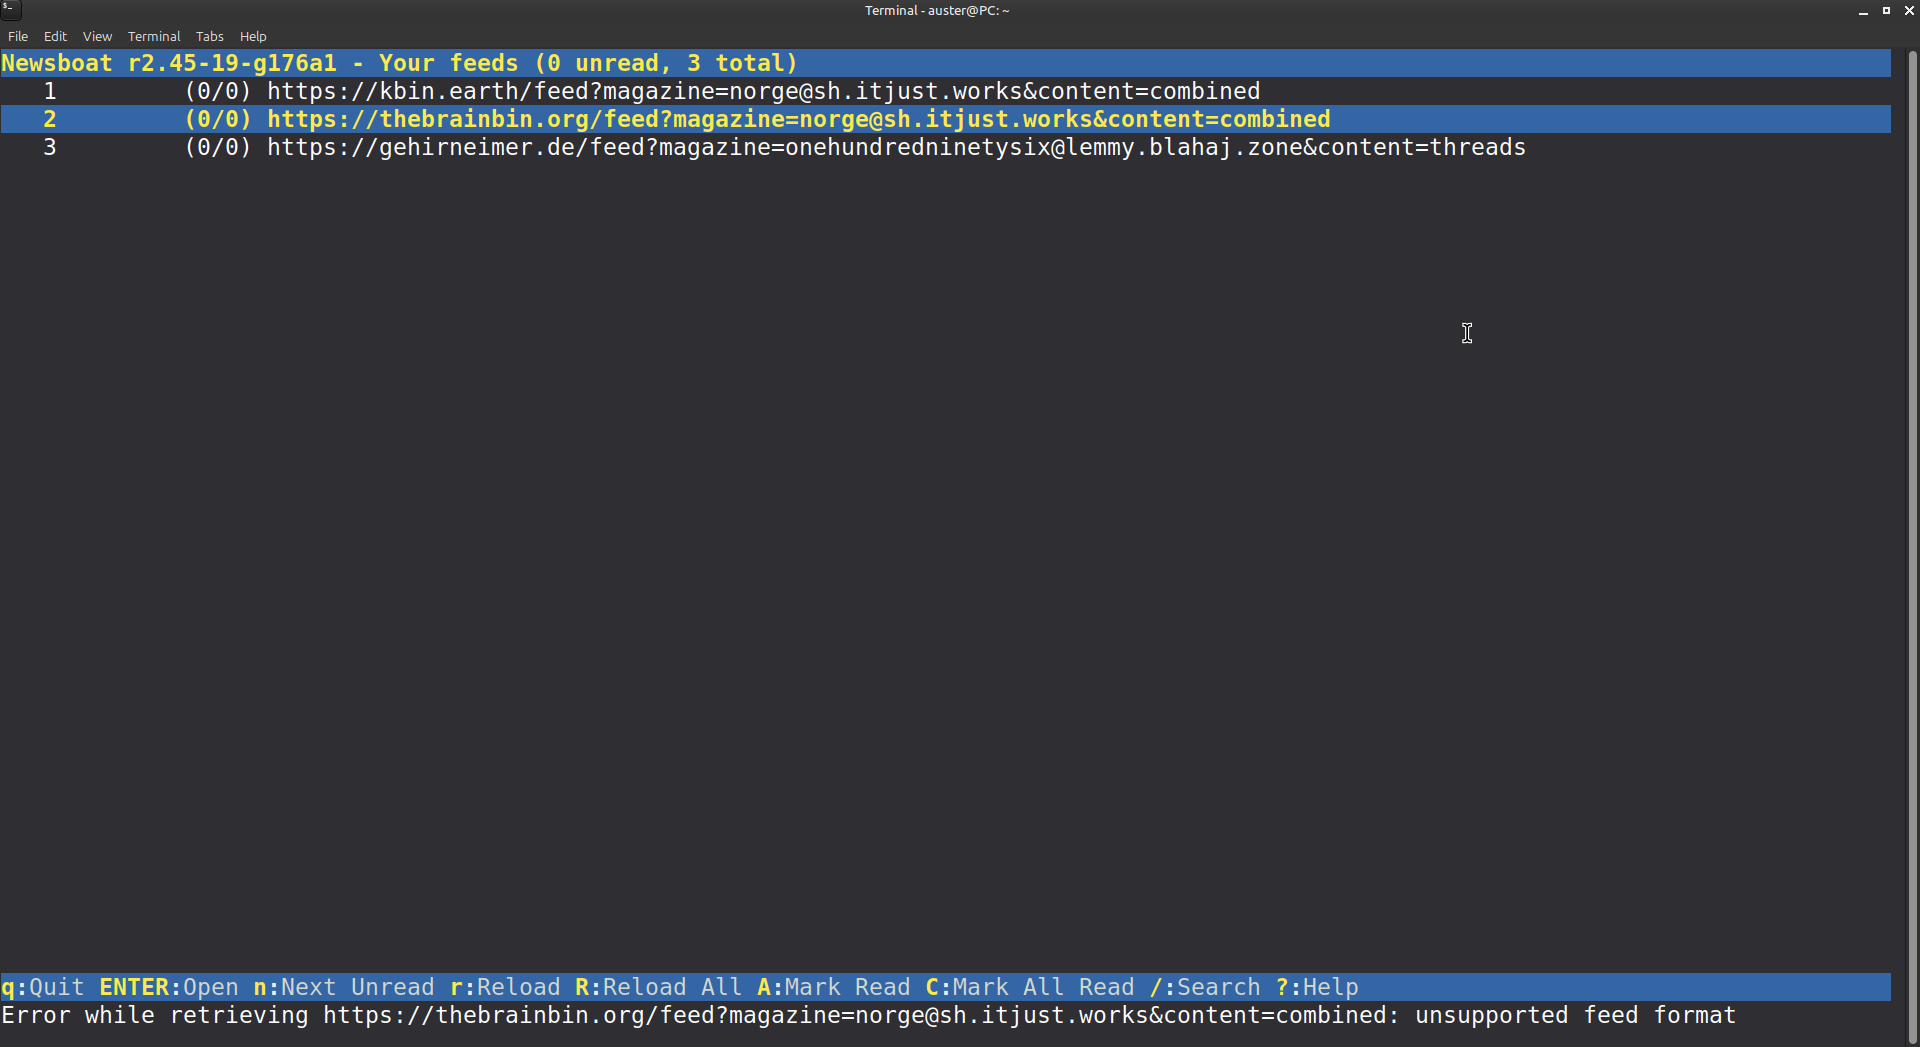
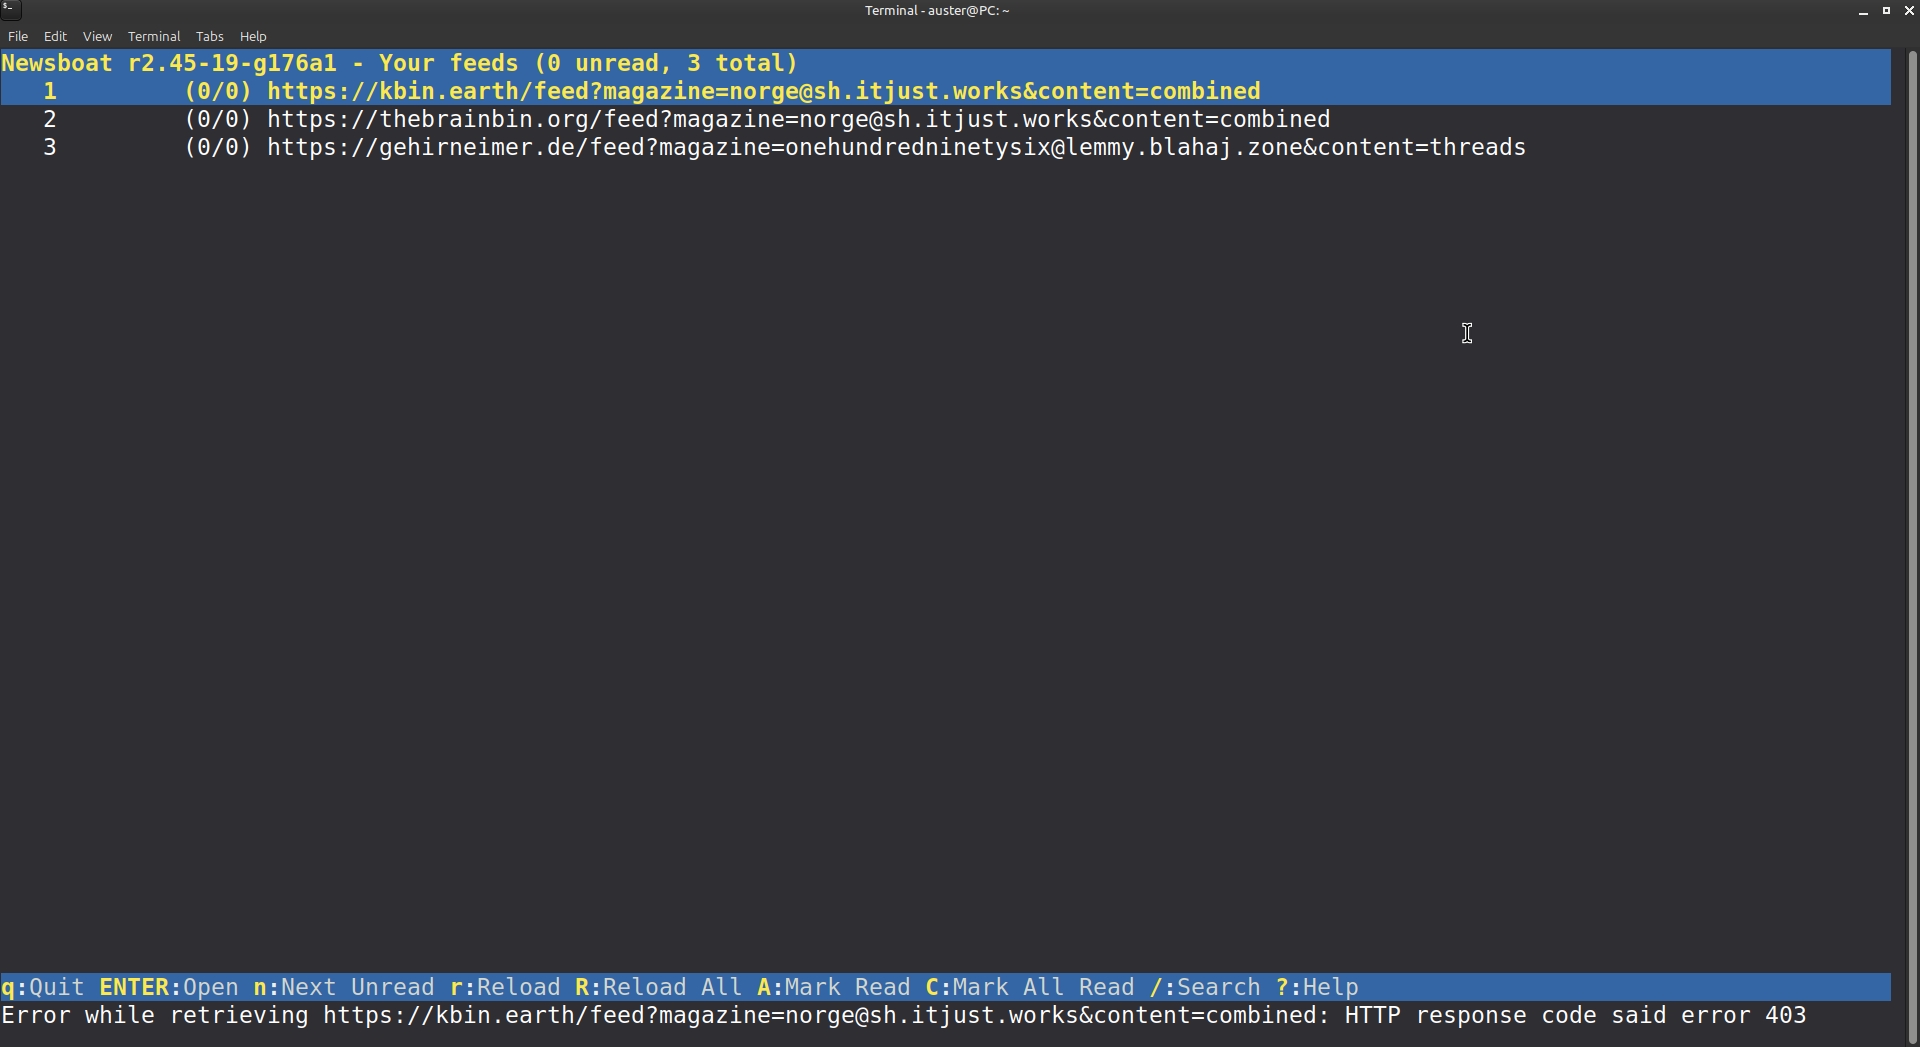
(2/4) Kbin.Earth's error on Feeder:
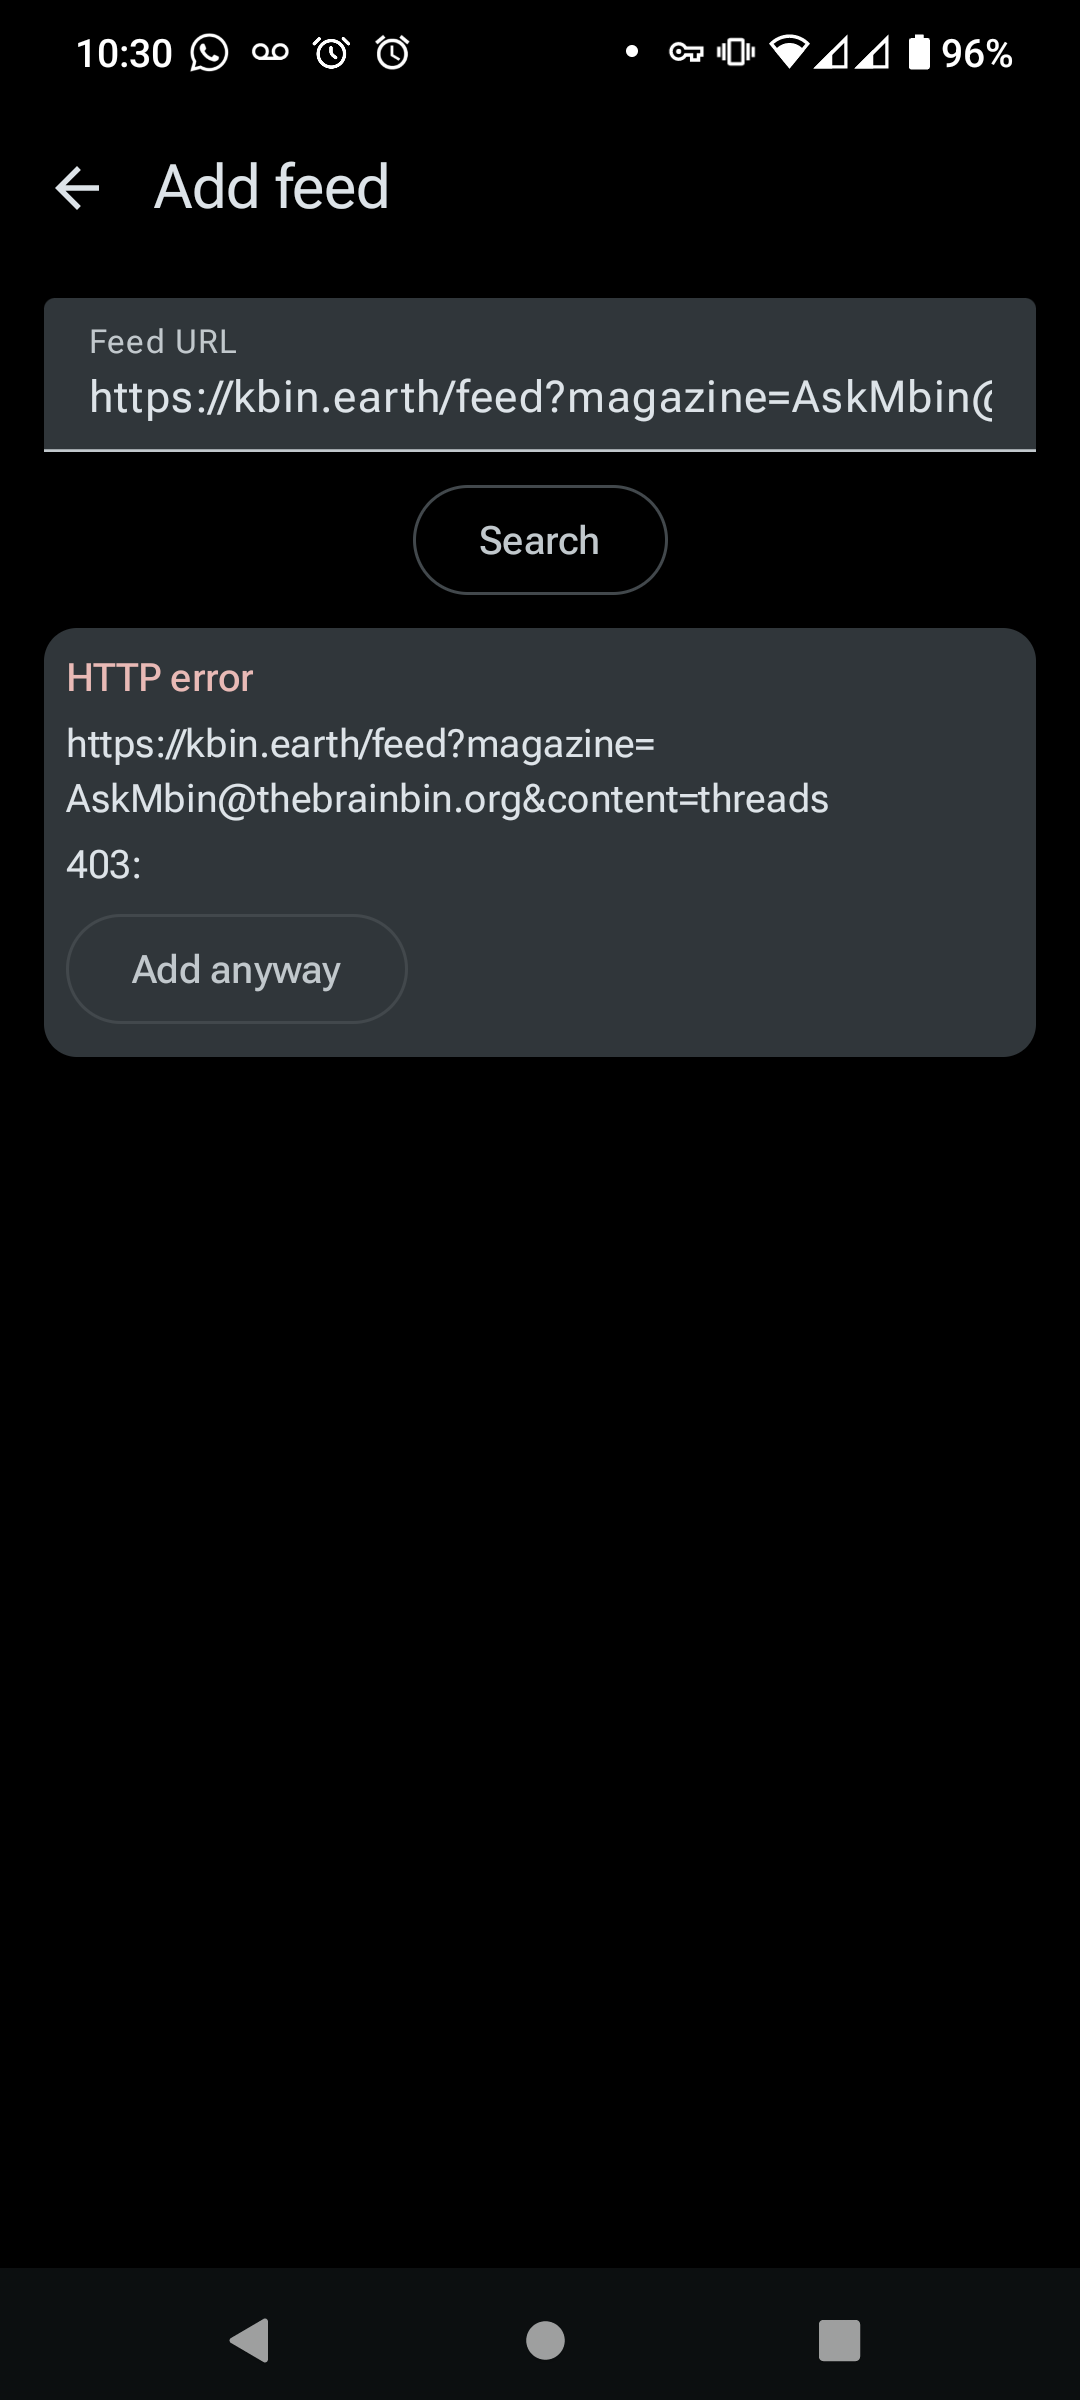
(1/4) Feeder tries to fetch info from the feed when adding it, and this error occurs for TBB:
btw this is the error from nextcloud news:
malformed xml string. parsing error: DOMDocument::loadXML(): Specification mandates value for attribute defer in Entity, line: 28 (2)
@blued_gear@fedia.io I am not sure what is going wrong. Xmllint says it is fine, the nextcloud news app says it cannot add it... Maybe just a missing schema reference or somethig... I am not sure.
@Auster@thebrainbin.org do you have the real error message?
If needed, I can record it in a few hours.
While the feature isn't added, what I do and would be what I suggest is to follow a given hashtag through RSS on mastodon.social (since biggest instance), and put a script to redirect the posts to your instance's search url, https://kbin.earth/search?search[q]=
Example hashtag RSS feed: https://mastodon.social/tags/mbin.rss
I think I had searched the links after I made the post.
But just made a post and checking across ~10 Lemmy instances, including the community's home instance, each got the post without me having to manually search the link. So maybe it was some temporary issue.
but your linked posts all appear in the magazine's home instance, so maybe they got issues federating somewhere, but your posts made it to these instances so the wider delivery to all magazine subscribers is on these instances, not on tbb...
No I am not aware of any problem... All of those are microblogs though, so maybe lemmy changed the handling of that...
Ok, so the issue is with exactly this field, because it is one that doesn't use the date field
Thank you.
However, my browser's language is set to English (United Kingdom), which normally gives monotonic dates.
Steps to reproduce:
mbin uses html date fields almost everywhere, so your browser settings should be able to change that I think