So noticed a few hours ago the feeds had changed.

However, each instance seems to behave differently from one another. Would have posted on Github if I could reproduce the errors consistently.

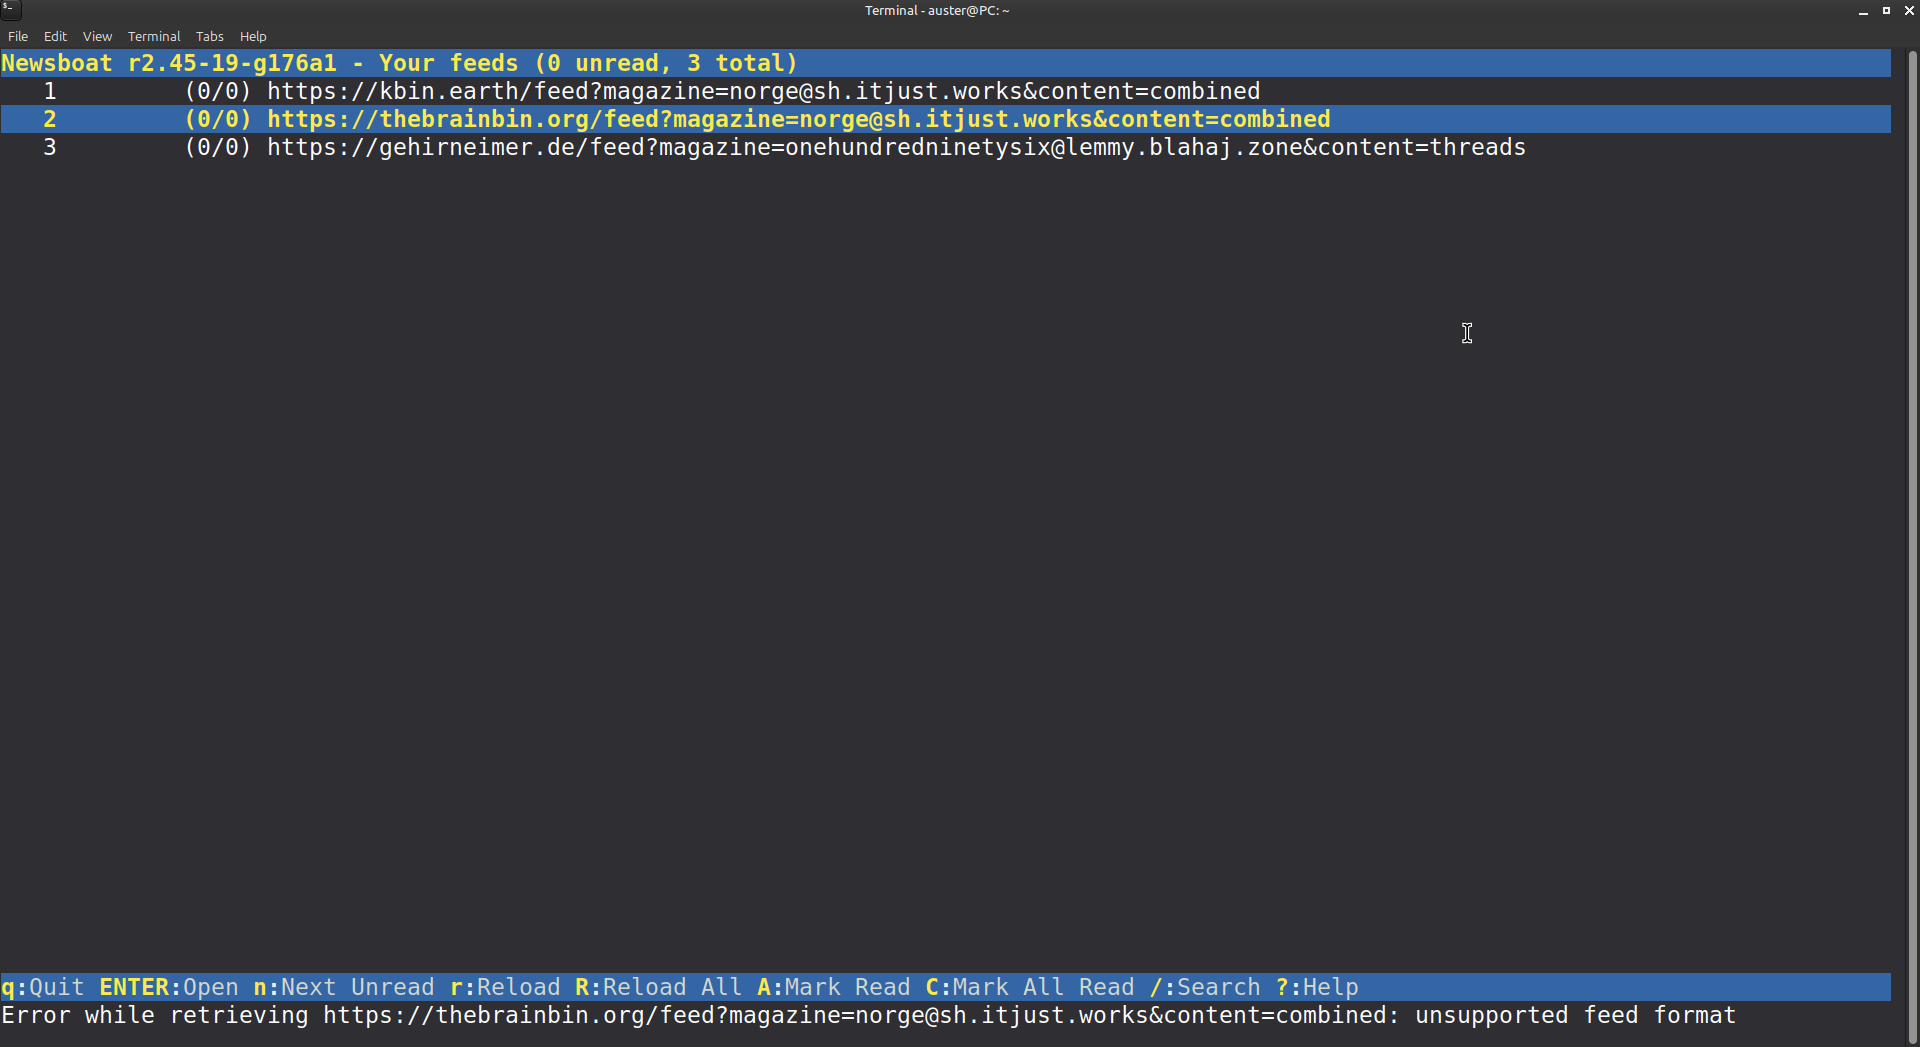
Here on TBB, any feeds give an unsupported format error.

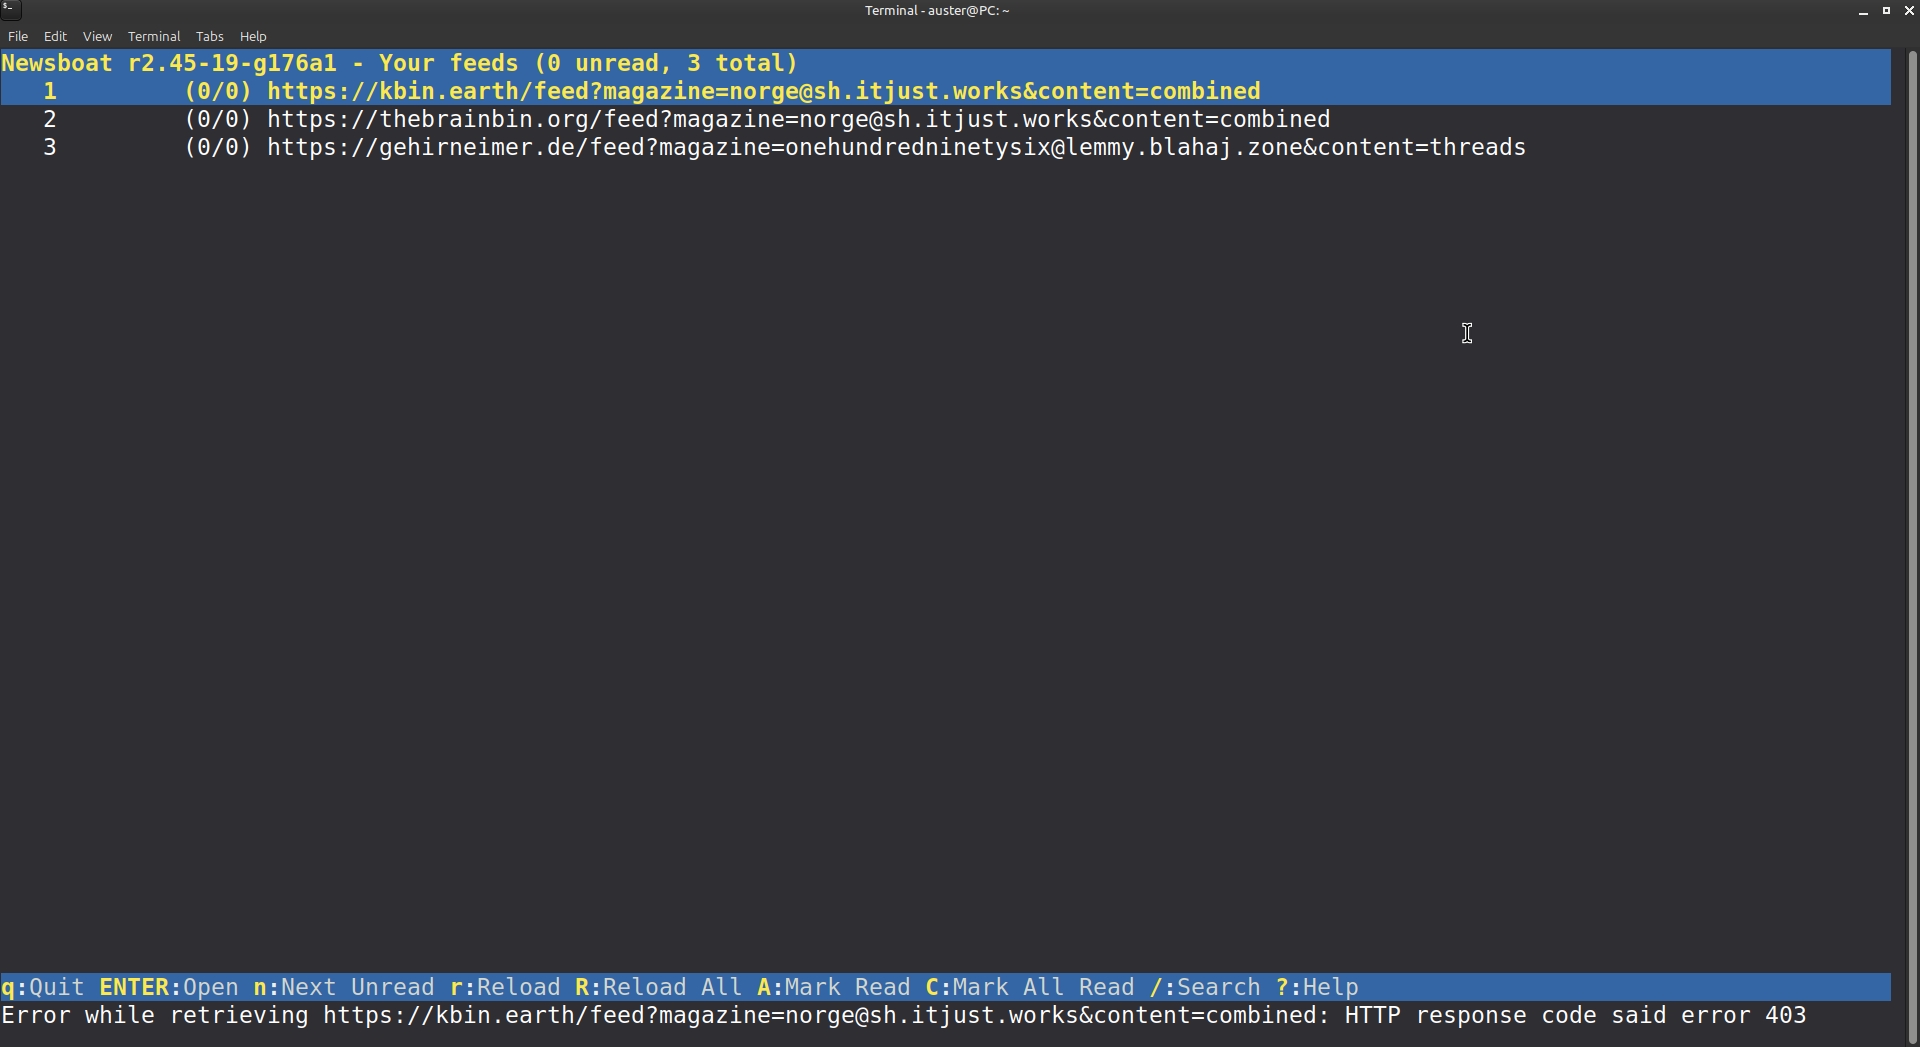
On Kbin.Earth, the feeds give a 403 error instead.

On GehirnEimer, which I don't have an account on but can be browsed without an account, feeds work fine.

Tested with:

you are viewing a single comment's thread
view the rest of the comments
[–] 1 point 1 week ago (8 children)

(3/4) (Just remembered I could send albums through my alt)TBB & kbin.earth errors on Newsboat when trying to reload feeds during my tests at the time of writing the post:
None

None

  • source
  • parent
  • hideshow 8 child comments
  • [–] [S] 1 point 1 week ago (6 children)

    (4/4) Remembered I could ask some AI to make things easier.

    For kbin.earth feed, Grok says it's Cloudflare bot protection, likely because neither Newsboat or Feeder pass a valid browser agent.

    For TBB, Grok for some reason had a hiccup, so asked GPT-5.4 on DuckDuckGo's AI bridge, and it said:

    The problem is that the URL is not returning a valid RSS/Atom feed. It’s returning an HTML login page instead, so feed readers see a normal webpage with , , etc., not feed XML. That’s why one reader says “no feeds on the page,” another says “unsupported feed format,” and another says “malformed xml string.”

    From the pasted page, the site is protected by login and the feed endpoint appears to require authentication or is redirecting to the login page. The presence of a CSRF token and sign-in form confirms the response is HTML, not feed data.

  • source
  • parent
  • hideshow 6 child comments
  • [–] 1 point 1 week ago (5 children)

    oh okay, well yeah I enabled the "force users to login" option, because the scrapers are just causing tremendous load otherwise. On gehirneimer it is currently disabled so maybe that is the sole reason?

  • source
  • parent
  • hideshow 5 child comments
  • [–] 1 point 1 week ago (2 children)

    So it is just the login requirement or did I miss something else? Allowing anonymous access to the endpoint would solve it then, but makes it also easy for scrapers to fetch content.

  • source
  • parent
  • hideshow 2 child comments
  • [–] [S] 2 points 1 week ago (1 child)

    Appears to have been the solution. Tested a link yesterday night, after BentiGorlich's comment on the spike graph, and the direct links are back to being login-protected, though now feeds seem to be working.

  • source
  • parent
  • hideshow 1 child comment
  • [–] [S] 1 point 1 week ago (1 child)

    Seems to be the case? Left an instance of Newsboat running as I went to do my chores, and just checking now, it already fetched a few communities' posts.

    Though it seems concerning to me that scrappers are getting past the current protections. (Hopefully I'm not one of them, considering how much I still follow...)

  • source
  • parent
  • hideshow 1 child comment