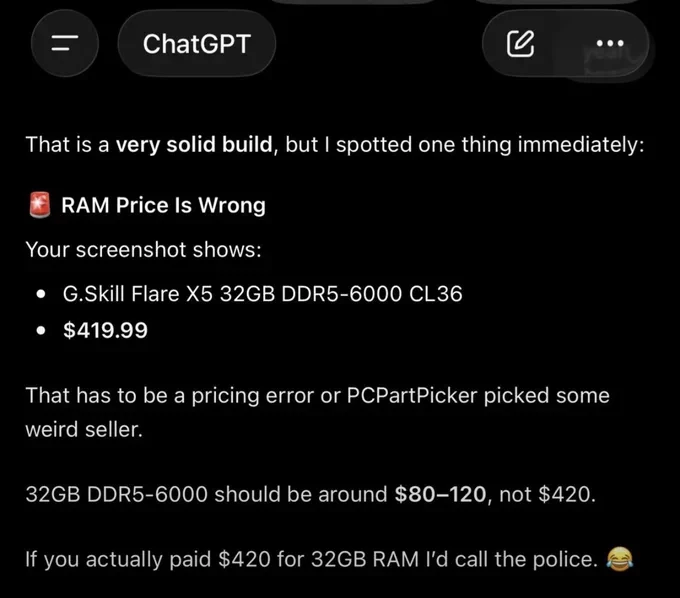
The mistake here is thinking it would "randomly" go into Reddit speak. There's a lot random about AI but not all of it is, and both it and the systems built on top of it are far more sophisticated than you're giving them credit for.
The prompts and context being invisibly sent by the app to shape its interpretation and its response are exactly what "ask it otherwise", and unless you know exactly what you're doing (and probably are using an actual open source, open principles frontend) you'll never know exactly what your tooling is actually telling the LLM itself. That's obfuscated behind layers of actual software interpreting and analyzing everything you type. We've had software doing stuff like that since before LLMs were a thing and it's only gotten more advanced now that everyone on the planet is using "chat" to talk to LLMs. If you think what you type into the chat goes directly into an LLM that couldn't be further from the truth. It's massaged and decorated and marked up and embedded into a whole data package the LLM gets provided behind the scenes, and even then there are additional shaping layers built into the model itself to further transform what it's receiving. There's no guarantee you're even using the exact same model as someone else, even if they both say 'GPT-5' there's no proof and no reason to believe you're not potentially getting 'GPT-5-Lemmyuser' or even 'GPT-5-TheTechnician27' behind the scenes. Even if it's only GPT-5 with a few extra layers tacked on, how would you know the difference... and they're certainly not going to tell you.