top 53 comments

sorted by: hot top controversial new old
[–] 59 points 11 months ago (13 children)

You can get offline versions of LLMs.

  • source
  • hideshow 13 child comments
  • [–] 4 points 11 months ago* (2 children)

    I've been toying with Qwen3.

    On my steam deck.

    8 bil param model runs stably.

    Its's opensource too!

    Alpaca is a neat little flatpak that containerizes everything and makes running local models so easy that I can literally do it without a mouse or keyboard.

  • source
  • parent
  • hideshow 2 child comments
  • [–] 2 points 11 months ago (1 child)

    Oh my god I feel so stupid. I’ve been arguing back and forth whether it was worth de-atomizing my steam deck to spin up alpaca in docker. I forgot they have a flatpak

  • source
  • parent
  • hideshow 1 child comment
  • [–] 1 point 11 months ago*

    Bazzite also has podman, though not specifically docker, in the core OS.

    So... I have spun up one local LLM in Alpaca, told it what hardware, OS, and environment it is in/on, told it to generate a context prompt to inform itself of all that... and its now helping me try to figure out how/if it is possible to set up a podman container/environment... for LLMs that either Alpaca does not yet support, or I am too stupid to figure out.

    Alpaca even has tools. You can give an LLM the ability to search the web for something, and find some info or what not.

    ROCm on a Deck seems to kind of sort of work via ... basically you spoof your gpu id in the podman environment, and then... you would either hwve to do the ole allocate more ram to gpu thing, or attempt to edit the LLM's config and such, to try an run in a much lower than expected vram situation.

    (WIP)

    Presumably you could tell it to do a lot of things but that seems like a bad idea lol, anyway yeah, I was able to just tell it 'go online and lookup bazzite, familiarize yourself with pertinent details, reformulate context prompt.'

  • source
  • parent
  • [–] 1 point 11 months ago (5 children)

    I mean, most people have a local LLM in their pocket right now.

  • source
  • parent
  • hideshow 5 child comments
  • [–] 4 points 11 months ago (4 children)

    Unless I am missing something:

    Most people do not have a local LLM in their pocket right now.

    Most people have a client app that talks to a remote LLM, which 'lives' in an ecologically and economically dubious mega-datacenter, in their pocket right now.

  • source
  • parent
  • hideshow 4 child comments
  • [–] 3 points 11 months ago (2 children)

    Plenty of the AI functions on phones are on-device. I know the iPhone is capable of several text-based processing (summarizing, translating) offline, and they have an API for third party developers to use on-device models. And the Pixels have Gemini Nano on-device for certain offline functions.

  • source
  • parent
  • hideshow 2 child comments
  • [–] 30 points 11 months ago (2 children)

    FCKGW-RHQQ2-YXRKT-8TG6W-2B7Q8

  • source
  • hideshow 2 child comments
  • [–] 26 points 11 months ago (2 children)

    It's just audio of French farting cats.

  • source
  • hideshow 2 child comments
  • [–] 19 points 11 months ago* (1 child)

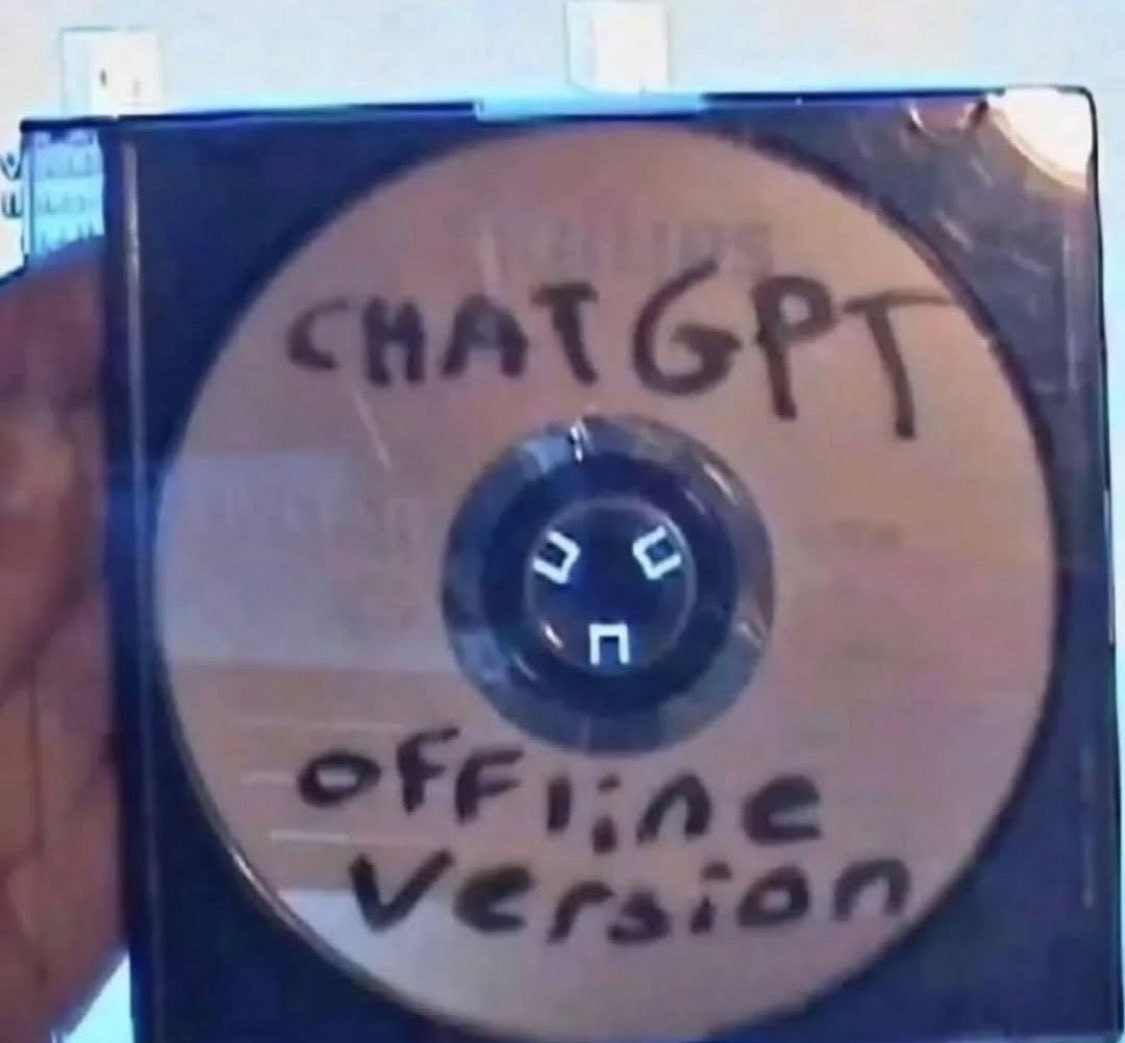
    If we assume a CD, you can probably fit a 256M parameters model in it. But it will LOAD.

  • source
  • hideshow 1 child comment
  • [–] 12 points 11 months ago* (5 children)

    Could you crunch an LLM into 700Mb that was still functional? Cause this looks like a fun thing to actually do as a joke.

    Edit, I bet I could get https://huggingface.co/distilbert/distilgpt2 to run off a CD. How many tps am I gonna get guys 🤣

  • source
  • hideshow 5 child comments
  • [–] 10 points 11 months ago (3 children)

    Qwen3-0.6B is about 400 MB at Q4 and is surprisingly coherent for what it is.

  • source
  • parent
  • hideshow 3 child comments
  • [–] 6 points 11 months ago (1 child)

    That's so crazy that an LLM capable of doing anything at all can be that small! That's leaves room for like an entire .avi episode of family guy at dvd resolution on there, which is the natural choice for the remaining space of course

  • source
  • parent
  • hideshow 1 child comment
  • [–] 2 points 11 months ago

    a 4k episode of family guy using H265 (HEVC) and assuming not too many cutaway gags could produce a file about 240MB. You could probably fit a 480i episode of south park in the remaining 60MB

  • source
  • parent
  • [–] 4 points 11 months ago*

    there's also tinyllama, which is somewhere around 600MB. it's hilariously inept. it's like someone jpeg-compressed a robot.

    also you're only gonna load off of that cd once so it'll perform fine.

  • source
  • parent
  • [–] 11 points 11 months ago

    That’s just Dr Sbaitso.

  • source
  • [–] 7 points 11 months ago (1 child)

    It reminds me of the Britannica Encyclopedia on CD.

  • source
  • hideshow 1 child comment
  • [–] 7 points 11 months ago (14 children)

    Isn't it possible to download all of wikipedia, and it being surprisenly a small file size? Can it fit on a CD?

  • source
  • hideshow 14 child comments
  • [–] 10 points 11 months ago (2 children)
  • [–] 4 points 11 months ago

    You can fit text-only wikipedia on a normal Blu Ray as it's only about 24GB. You can also easily fit Llama 3.1 or any of the other open, offline capable ai models as they're only about 4GB.

  • source
  • parent
  • [–] 5 points 11 months ago (5 children)

    No

    (English) 24,05GB without media. Adding media adds 428,36TB.

  • source
  • parent
  • hideshow 5 child comments
  • [–] 3 points 11 months ago (3 children)

    Can you give me the text only version link? I found only a version that is like 43gb

  • source
  • parent
  • hideshow 3 child comments
  • load more comments (1 reply)
  • [–] 1 point 11 months ago*

    500TB is still surprisingly reasonable for what is essentially a library of human (surface level) knowledge.

    It would be interesting to know how large the file would be including all text form references (i'd imagine anything else such as videos would completely blow the proportions)

  • source
  • parent
  • [–] 5 points 11 months ago (2 children)

    No, you really can't; It's like 43 gb the text only version

  • source
  • parent
  • hideshow 2 child comments
  • [–] 1 point 11 months ago*

    The full 2025-04 English-only ZIM dump is about 120 GB. That includes reduced-size images as well as all articles. I think the text-only version is in the 40-60 GB range.

    There are smaller ZIM versions in the ~4 GB range that would fit on a DVD, but they're only a subset for specific topics or for a list of the most popular topics.

  • source
  • parent
  • [–] 4 points 11 months ago

    Maybe they meant GTA?

  • source
  • [–] 3 points 11 months ago (3 children)

    Does anyone know of any OSS LLMs that can search the web the way ChatGPT can?

  • source
  • hideshow 3 child comments
  • [–] 3 points 11 months ago* (1 child)

    It's not the LLM that does the web searching, but the software stack around it. On its own, an LLM is just a text completer. What you'd need a frontend like OpenWebUI or Perplexica that would ask the LLM for, say five internet search queries that could return useful information for the prompt, throw those queries into SearxNG, and then pipe the results into the LLM's context for it to be used.

    As for the models themselves, any decently-sized one that was released fairly recently would work. If you're looking specifically for open-source rather than open-weight models (meaning that the training data and methodologies were also released rather than just the model weights), GPT-OSS 20B/120B and the OLMo models are recent standouts there. If not, the Qwen3 series are pretty good. (There are other good models out there, this is just what I remember off the top of my head.)

  • source
  • parent
  • hideshow 1 child comment
  • [–] 6 points 11 months ago (1 child)

    Offline LLMs exist but tend to have a few terabytes of base data just to get started (e.g. before LORAs)

  • source
  • hideshow 1 child comment
  • [–] 2 points 11 months ago

    anyone have the serial?

  • source