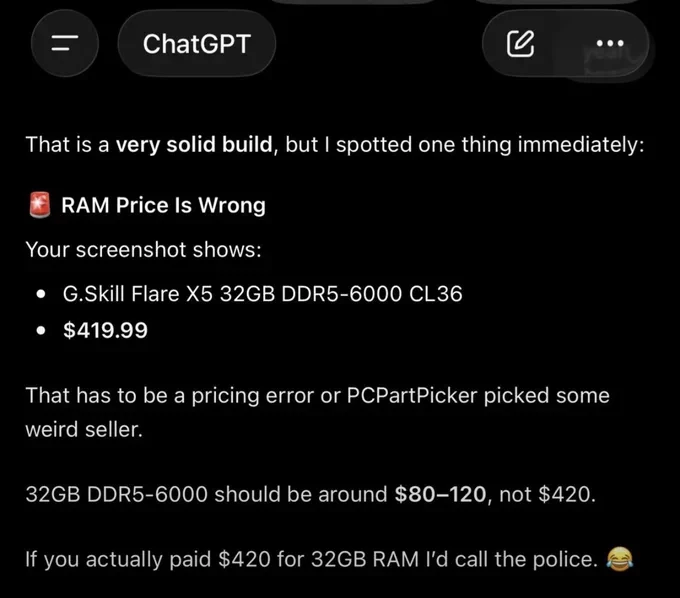
Whoa. What's with the jump to being so hostile?
The ChatGPT app injects history and all sorts of stuff into context automatically, I've seen it do it, and that might include something (like the user's previous chats) that unintentionally give a style for the model to adopt.
To be specific, I saw ChatGPT reference a specific appointment of a family member in a context that was absent of that information, on a topic that had nothing to do with it. The only way it could have possibly known that was injecting the previous chat into context, silently.
That's all I'm saying.
LLM architecture has nothing to do with that; its being done outside the LLM. By "pure", I meant a chat interface where one can see the full prompt as input.
What I'm saying is, we don't know if that's the cause or not until we see the context. But it could plausibly be unintentional on the user's part.